`)
- [Use maxint to bound integers.](https://github.com/pytorch/pytorch/pull/96121) (helps CrystalDPR enablement get past MAX\_INT tests on unbacked SymInts)
- [Don’t guard on the exact int value on conversion to bool](https://github.com/pytorch/pytorch/pull/96008) (overspecialization fix, affected multiple real models including OpenNMT)
- [Fix training enablement in AOTAutograd](https://github.com/pytorch/pytorch/pull/95975) (the promised training fix from last week)
- **Export is getting a higher level constraints API.** This adds a new `constraints` kwarg to export, which lets you declare things like “these dimensions are dynamic” (`dynamic_dim(y, 0)`). See [Add higher level export constraints api](https://github.com/pytorch/pytorch/pull/96338) for the details.
- **GCP benchmarking.** It’s here! Dynamic shapes benchmarking for dashboard is unblocked but hasn’t been started yet. This will probably be done concurrently with [Improving performance dashboard latency / ROI - Google Docs](https://docs.google.com/document/d/1jihUROLFah_Umx4962xRsp7xexqBAG268MVN66HRH-I/edit#heading=h.g48wwickx5dz)
- **State of real world model enablement.**
- LLaMa and InstructPix2Pix are added to torchbench: [https://github.com/pytorch/benchmark/pull/1446](https://github.com/pytorch/benchmark/pull/1446) and [Add instructpix2pix model by xuzhao9 · Pull Request #1451 · pytorch/benchmark · GitHub](https://github.com/pytorch/benchmark/pull/1451) They haven’t been enabled for our regular benchmark runs yet, stay tuned!
- OpenNMT arange minimal repro runs without error and does not overspecialize. Vince was giving the whole model a try, but there are some problems with guard provenance: [OpenNMT doesn't work with dynamic torch.compile · Issue #93468 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/93468#issuecomment-1462178765)
- fmo-mt reported that huggingface BERT+TransformerEncoderLayer was failing with dynamic shapes. PR to fix is in review. Issue: [Runtime error of TorchDynamo compiled model (unflatten) · Issue #95868 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/95868) Fix: [Don’t specialize torch.Size with specialize\_int = False #96419](https://github.com/pytorch/pytorch/pull/96419). This also would be fixed if we fixed the HF induced graph break, tracked at [[Dynamo] HuggingFace transformers configuration\_utils graph break workaround · Issue #96205 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/96205)
- Someone tried to run this on MNIST, and apparently dropout doesn’t work with symbolic sizes. [Torch Dynamo backend compilation error with dynamic = True · Issue #96469 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/96469)
- If the optimized SDPA Transformer implementation in PyTorch is used, this doesn’t work with symbolic sizes. [torch.compile(dynamic=True) does not work with a simple Transformer + embedding at inference · Issue #96414 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/96414)
- Some folks at IBM are interested in getting huggingface T5 working with dynamic shapes. They ran into some issues, both dynamic and non-dynamic related, many of which are now fixed. Not sure what the current status is. Issue: [torch.compile fails when compiling a T5-style model with HF interfaces · Issue #96130 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/96130)
- No updates: MaskRCNN, Detectron2, wav2vec2, fused boolean mask update
- **How far away from dynamic shapes “shipping”?** Soumith defines shipping as “we show meaningful end-to-end speed ups in training due to dynamic shapes” (possibly with s/training/inference/ as a milestone on the way to this goal), but at the same time, we are in the business of creating generic infrastructure that works for everything, not just cherry-picked models.
- On training, the metric here is difficult to define, because models don’t really have dynamic shapes. So to evaluate real world models, we would really have to take models that _do_ have dynamic shapes in training (e.g., can be observed by the fact that otherwise they blow out the compile cache.) We don’t have this list of models: we need to sweep the benchmark suite and find out (although there’s a decent chance models involving bounding boxes like detectron2 and MaskRCNN are likely to be on this list). Plus, you have to make sure you’re running enough iterations, with real enough data, to actually exercise this data dependence! However, it’s possible things are working today _already_, we just don’t actually have the data.
- On inference, the value add of dynamic shapes is much easier to articulate: people want to vary batch size (for adaptive batching), sequence length (because text input is variable size) and image size (ditto), and we have already shown dynamic shapes works end-to-end for models like BERT. The flip side of the coin is if dynamic shapes is “shipped by default”; and this involves adaptively turning on dynamic shapes when we detect situations where we have potential to blow out our compile cache–this is probably a week or two of full time work to finish off.
The numbers:
- **Model status on master.** See also [Symbolic shapes work items tracker - Google Sheets](https://docs.google.com/spreadsheets/d/1-ghURoD6tzTushbCb22tFd5B5uNg7HSxVG4dQBwoaFA/edit?pli=1#gid=188393643)
- aot\_eager inference: -1 (-1 WoW). The regression is a new sympy RecursionError in vision\_maskrcnn induced by `unspecialize_int=False` when running `reshape(torch.empty(s1, (s0 + 1)//2, 2), (s1, s0))`. [Logs](https://github.com/pytorch/pytorch/actions/runs/4388735265/jobs/7685929259)
- aot\_eager training: -2 (-2 WoW). The regression are also two sympy RecursionError induced by `unspecialize_int=False`. The botnet26t\_256 looks like the same cause (reshape) as the vision\_maskrcnn, but eca\_botnext26ts\_256 looks like some sort of modulus problem. [Logs](https://github.com/pytorch/pytorch/actions/runs/4388735265/jobs/7685929474)
- inductor inference: -4 (+6 WoW, or unchanged, depending on how you count it). We regressed this stat with `specialize_int = False`, but we fixed most of the regression in time for the report. We did one trace: volo\_d1\_224 is now fixed, but convit\_base is failing with a new error “TypeError: Cannot convert symbols to int”
- inductor training: -9 ( **NEW!** ). Training is enabled in CI! The bulk of the current failures are either `'float' object has no attribute '_has_symbolic_sizes_strides'` (this is due to AOTAutograd sending graphs with SymFloat inputs, contrary to inductor’s input contract). There is one accuracy failure with rexnet\_100; however, this model is known to be flaky accuracy with static shapes too.
- **Opinfo tests on symbolic shapes.**
- `pytest test/test_proxy_tensor.py -k test_make_fx_symbolic_exhaustive` - **566 passed (+4 WoW)**, 524 skipped (+1 WoW), 192 xfailed (-3 WoW)
- `pytest test/functorch/test_aotdispatch.py -k test_aot_autograd_symbolic_exhaustive` -
- **Graph breaks on master.** 0ish (unchanged). hf\_Longformer and AllenaiLongformerBase are still diverging intermittently. Graph breaks will be in CI and we will resolve this one way or another.
- **Tracing cost of enabling dynamic shapes (aot\_eager).** Mean: 15s (-5s), Max: 168s (-72s WoW). Not really sure where the speedups are coming from, but we’ll take it!
- Repro command: `benchmarks/dynamo/run_delta.sh --backend aot_eager --devices cuda --cold-start-latency --ci`
## Known problems
Unchanged from [State of symbolic shapes branch - #45 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/45#known-problems-3)
## What’s coming next?
- ezyang: burning down the biggest blocker bugs (right now, that’s float handling). Also need to setup perf CI.
- Chillee: unclear
- bdhirsh: per-dispatch key mode stacks and then torchquant/DTensor PT2 support
- voz: finishing up in flight work
- jbschlosser: enabling dynamic shapes for nested tensor
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [March 19, 2023, 1:50am UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/47 "2023-03-19T01:50:09Z")
# State of symbolic shapes: Mar 18 edition
Previous update: [State of symbolic shapes branch - #45 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/45#state-of-symbolic-shapes-mar-12-edition-1)
## Executive summary
For your information:
- `specialize_int` now defaults to `False`. Every overspecialization known a week ago is fixed; there is one new undiagnosed overspecialization at [Torch Dynamo backend compilation error with dynamic = True · Issue #96469 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/96469)
- If you run dynamic=True on a model this week, what should you expect? It shouldn’t error, but there is a decent chance you will run into accuracy problems ([torch.compile() accuracy minifier breaks when using dynamic shapes · Issue #96971 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/96971)) or performance problems ([torch.compile (torch dynamo specifically) failing for simple GNNs trained with Neighbor Sampling (dynamic batches) · Issue #94640 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/94640)). We are actively investigating these issues (but are somewhat blocked by the minifier not working), let us know if you find more.
Stuff happens:
- **We keep fixing bugs.** Some highlights:
- [Turn off split reductions for dynamic shapes](https://github.com/pytorch/pytorch/pull/96850) (fixes `RuntimeError: mat1 and mat2 shapes cannot be multiplied (10x14817 and 14797x16)`)
- [Propagate dynamo dynamic\_shapes config to backwards](https://github.com/pytorch/pytorch/pull/96771) (fixes `AssertionError: free variables NYI: s0`)
- [Correctly use PythonPrinter for generating wrapper code referencing sympy](https://github.com/pytorch/pytorch/pull/96710) (fixes `NameError: name 'ceiling' is not defined`)
- [Add missing ceil for libdevice in triton](https://github.com/pytorch/pytorch/pull/96709) (fixes `CompilationError: math.ceil`)
- [Only allow SymInt across partitioner boundaries, and fixes](https://github.com/pytorch/pytorch/pull/96653) (fixes `'float' object has no attribute '_has_symbolic_sizes_strides'`)
- **Notable unfixed bugs.**
- Guards generated by inductor in backwards don’t do anything. We’ve known this for a while, but this has started showing up for real in bug reports. Usually, we didn’t want the specialization anyway, but this bug means that instead of getting recompiles, we will just blindly run code at the wrong size; sometimes you still get an error (like size mismatch between 14817 and 14797).
- Minifier with dynamic shapes doesn’t work! Even our users have noticed.
- Hoisting padding compute still doesn’t work. pnasnet5large
is still generating fairly horrible code, even with the ceil fix [Add missing ceil for libdevice in triton by ezyang · Pull Request #96709 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/96709) . Natalia knows how to make hoisting more aggressive so that it can also hit padding compute.
- **Open source shout-out.** Thanks ZhongYingMatrix for helping fix generated Inductor Python wrappers for SymInts in [handle SymInt shape/input when debugging in dynamic shape by ZhongYingMatrix · Pull Request #96645 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/96645)
- **State of real world model enablement.**
- [BERT+TransformerEncoderLayer problem with overspecialization](https://github.com/pytorch/pytorch/issues/95868) is fixed!
- [MNIST problem](https://github.com/pytorch/pytorch/issues/96469) is now failing due to over-specialization in backwards + lack of backward guards
- [TransformerEncoder SDPA coverage problem](https://github.com/pytorch/pytorch/issues/96414) is fixed! (Thanks Driss!)
- [HuggingFace T5-style model that IBM is working on has accuracy issue](https://github.com/pytorch/pytorch/issues/96971). This one is weird and hard to localize because the accuracy minifier is not working.
- The export team has been asking about how to export MaskRCNN, and in particular Yidi Wu has submitted a PR requesting to [add while loops](https://github.com/pytorch/pytorch/pull/96899) to our control flow operators. The while loop is motivated by the fact that MaskRCNN iterates through bounding boxes to perform an expensive prediction, and they need early exit as soon as they’ve found what they’re looking for.
- I looked into what kind of dynamism folks wanted for InstructPix2Pix, and it seems like they want to dynamically vary the image height/width. It is not clear if we can _actually_ easily support this; I don’t understand diffusion model architecture well enough to know how to compile a size agnostic model; it seems like you need to make actual architecture changes to work on different sizes.
- No updates: LLAMA, OpenNMT, Detectron2, wav2vec2, fused boolean mask update
- **PyTorch core offsite happened!** Some things we discussed:
- **Split reductions.** We have a strategy for dynamic shapes split reductions now. Split reductions refer to a performance optimization when compiling reductions where the non-reduced axis is too small for us to fully occupy all blocks on GPU by simply assigning each reduction to a block. When the number of elements to reduce is large, we want to _split_ these large reductions into smaller reductions for better occupancy. Split reductions substantially improve performance when they apply. Currently, split reductions cause us to specialize on all of the input shapes involved; to support dynamic shapes, we should instead guard only the determination if an axis is large or not. We may perform this as part of an Inductor-specific decomp, if it is simpler to do so. Thanks Natalia for guidance on how to do this.
- **Supporting while loops as control flow operator.** Yidi Wu wants to while\_loop to our control flow operators set: [[functorch][experimental] Support while\_loop in eager\_mode by ydwu4 · Pull Request #96899 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/96899) I didn’t like it. We spent a bunch of time discussing this in the offsite, and we settled on this: there is utility in pushing control flow with restrictions to Inductor, as it gives Inductor opportunities to optimize (instead of forcing a hard barrier before and after the control flow.) The important thing is to restrict the operator sufficiently, so that it can be treated as “just a complicated operator”. Furthermore, to propagate the operator all the way to Inductor, all of our passes must know how to handle it (most notably, autograd, functionalization and batching). To put a control flow operator into PyTorch proper, it must live up to this standard; otherwise it should just be treated as some ad hoc, inference export only unblocker.
- **Asserts.** We spent some time discussing how asserts (and debug logging) should be implemented in our IR, prompted by Tugsuu’s work in export on the topic. The challenge is twofold: first, asserts are side effectful operations, but the current design of our IR is functional and would permit us to DCE all asserts. Second, we don’t want asserts/debug logs to interfere with normal optimizations that we are doing in programs. Our current thinking is that we will do a GHC-style “world token” to represent asserts and debug logs. In short, every assert/debug log will take a synthetic, zero-size “world token” tensor as input, and produce a new world token as output. The overall graph takes a world token and produces a world token. The resulting graph looks like this:
```auto
def f(x, world0):
b = torch.any(x)
world1 = torch._assert(b, world0)
y = x + 1
return (y, world1)
```
World tokens done in this style enforce a consistent ordering between all asserts and logs (it is likely confusing to users if log messages get reordered) and don’t require any special handling from optimization passes (as these are just “normal” data dependencies.) No new concept of control dependencies is added.
The numbers:
-
- **Model status on master.** See also [Symbolic shapes work items tracker - Google Sheets](https://docs.google.com/spreadsheets/d/1-ghURoD6tzTushbCb22tFd5B5uNg7HSxVG4dQBwoaFA/edit?pli=1#gid=188393643)
- aot\_eager inference: -1 (unchanged). Still vision\_maskrcnn sympy error from `reshape(torch.empty(s1, (s0 + 1)//2, 2), (s1, s0))`.
- aot\_eager training: -2 (unchanged). Still botnet26t\_256 and eca\_botnext26ts\_256.
- inductor inference: -6 (-2 WoW). The regression in PegasusForCausalLM and PegasusForConditionalGeneration is from the bug fix to avoid specializing on torch.Size. These models error in the same way as convit\_base: “TypeError: Cannot convert symbols to int”
- inductor training: -2 (+7 WoW). This was where most of our activity was this week! There’s only two failures left: pytorch\_unet (TypeError: unhashable type: ‘SymInt’) and tf\_efficientnet\_b0 (NameError: name ‘s1’ is not defined)
- **OpInfo tests on symbolic shapes.**
- `pytest test/test_proxy_tensor.py -k test_make_fx_symbolic_exhaustive` - **571 passed (+5 WoW)**, 524 skipped (unchanged), 187 xfailed (-5 WoW)
- `pytest test/functorch/test_aotdispatch.py -k test_aot_autograd_symbolic_exhaustive` - **324 passed (+4 FoF)**, 148 skipped (+1 FoF), 169 xfailed (-4 FoF)
- **Graph breaks on master.** Will’s graph break infrastructure is checked into master, but not yet running on dynamic shapes. The also appear to be turned off for aot\_eager. I did a run with them turned on for dynamic shapes. [https://hud.pytorch.org/pr/97107](https://hud.pytorch.org/pr/97107)
- inductor: -7 ( **NEW!** ). Weirdly, using inductor as the backend seems to change dynamo behavior. These models did worse: XLNetLMHeadModel, poolformer\_m36, visformer\_small, volo\_d1\_224, drq, functorch\_maml\_omniglot, maml\_omniglot. We also had one model do better (less graph breaks): hf\_Reformer
- **Tracing cost of enabling dynamic shapes (aot\_eager).** `benchmarks/dynamo/run_delta.sh --backend aot_eager --devices cuda --cold-start-latency --ci`. Mean: 12s (-3s WoW), Max: 151s (-17s WoW)
## What’s coming next?
- ezyang: bug burn down (esp diagnose GNN perf problem), perf CI
- Chillee: fix dynamic shapes minifier
- bdhirsh: pre-autograd tracing, torchquant/DTensor PT2 support
- voz: dynamic shapes dynamo marking guardsy stuff
- jbschlosser: dynamic shapes for nested tensor, into E2E compilation
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [March 26, 2023, 5:39pm UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/48 "2023-03-26T17:39:03Z")
# State of symbolic shapes: Mar 26 edition
Previous update: [State of symbolic shapes branch - #46 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/46#state-of-symbolic-shapes-mar-18-edition-1)
## Executive summary
This was a sleepy week. There’s a lot of activity going on in various dynamic shapes bugs on the bug tracker, though less fixes than I would have liked.
- **Some bug fixes:**
- [DCE inference graphs too](https://github.com/pytorch/pytorch/pull/97275)
- [Make split reduction warning only emit once](https://github.com/pytorch/pytorch/pull/97112)
- [Don’t run fallback if symbolic sizes in fake tensor](https://github.com/pytorch/pytorch/pull/97148)
- [[inductor] hoist symbolic padding expressions](https://github.com/pytorch/pytorch/pull/97099)
- Horace has a dynamic shapes minifier fix PR up at: [Fix minifier for symbolic shapes by Chillee · Pull Request #97428 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/97428) patch it in if you need to minify stuff
- Brian has posted initial draft of AOTDispatch: [https://github.com/pytorch/pytorch/pull/97540](https://github.com/pytorch/pytorch/pull/97540)
- **State of real world model enablement.**
- [MNIST with dynamic batches](https://github.com/pytorch/pytorch/issues/96469) triggering lots of workstreams, check out [Notes from training mnist dynamic=True - Google Docs](https://docs.google.com/document/d/15dBE3-fJRNJ7FrhL-tprBelrFH4O4r4sR-wds06sjRo/edit#)
- [HuggingFace T5 accuracy failure](https://github.com/pytorch/pytorch/issues/96971) has a repro, ready to investigate!
- [wav2vec2 inference](https://github.com/pytorch/pytorch/issues/91719) is working again
- [torch\_geometric performance](https://github.com/pytorch/pytorch/issues/94640) - a lot of subtasks:
- puririshi98’s GCN NeighborSampling minimal test is only slightly faster with static compile (and only after fixing graph break); dynamic shapes is slower even with graph break fix, it could be split reductions, but even with static there is not much payoff.
- rusty1s’s SAGEConv minimal test is not faster E2E even with static compile. pytorch-geometric has benchmarks at [Compiled Graph Neural Networks — pytorch\_geometric documentation](https://pytorch-geometric.readthedocs.io/en/latest/tutorial/compile.html#benchmark) showing E2E speedup, I don’t know how to reproduce it yet.
- In any case, they are affected by overspecialization in backwards, maybe. [torch.compile (torch dynamo specifically) failing for simple GNNs trained with Neighbor Sampling (dynamic batches) · Issue #94640 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/94640#issuecomment-1479101869)
- [vision\_maskrcnn](https://github.com/pytorch/pytorch/issues/93598) (also [`torch.compile` + `torch.no_grad` not working for Mask R-CNN · Issue #97340 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/97340)) - although it’s failing accuracy in the benchmark script, it can be run locally after [SymIntify roi\_align by ezyang · Pull Request #7448 · pytorch/vision · GitHub](https://github.com/pytorch/vision/pull/7448) and some massaging with static by default. Repro script at [maskrcnn.py · GitHub](https://gist.github.com/ezyang/2024bfdb6a2161f65ad7820264057fe7)
- No update: LLAMA, InstructPix2Pix, detectron2, OpenNMT, fused boolean mask
The numbers:
- **Model status on master.** See also [Symbolic shapes work items tracker - Google Sheets](https://docs.google.com/spreadsheets/d/1-ghURoD6tzTushbCb22tFd5B5uNg7HSxVG4dQBwoaFA/edit?pli=1#gid=188393643)
- aot\_eager inference: -1 (unchanged). Still vision\_maskrcnn sympy error from `reshape(torch.empty(s1, (s0 + 1)//2, 2), (s1, s0))`.
- aot\_eager training: -2 (unchanged). Still botnet26t\_256 and eca\_botnext26ts\_256.
- inductor inference: -7 (-1 WoW). The regression is tf\_efficientnet\_b0 from [https://github.com/pytorch/pytorch/pull/97099](https://github.com/pytorch/pytorch/pull/97099); this is a case of temporarily breaking things to move globally in a better direction
- inductor training: -1 (+1 WoW). pytorch\_unet was fixed, leaving tf\_efficientnet\_b0 (NameError: name ‘s1’ is not defined)
- **Graph breaks on master.** Sorry, CI is still not updated to do dynamic, maybe next week. We think the graph breaks are not super high priority at the moment, unless they are also affecting performance.
- **Tracing cost of enabling dynamic shapes (aot\_eager).** `benchmarks/dynamo/run_delta.sh --backend aot_eager --devices cuda --cold-start-latency --ci`. Mean: 12s (unchanged), Max: 153s (+2 WoW, probably noise)
## What’s coming next?
- Horace on PTO next week
- Voz: finish refactor at [https://github.com/pytorch/pytorch/pull/97164](https://github.com/pytorch/pytorch/pull/97164), then shape\_env + 2 tier guard cache
- Avik: Work on dynamic\_dim(x, 0) \<= 2 constraints API after Voz finishes refactor
- Brian: More AOTDispatch
- Edward: Not sure, flag me if you’re blocked
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [April 2, 2023, 10:02pm UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/49 "2023-04-02T22:02:09Z")
## State of symbolic shapes: Apr 1 edition
Previous update: [State of symbolic shapes branch - #48 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/48#state-of-symbolic-shapes-mar-26-edition-1)
## Executive summary
- **Some bug fixes:**
- [Propagate inductor guards to ShapeEnv](https://github.com/pytorch/pytorch/pull/97777) - this should have been fixed long ago, but c’est la vie. Figuring out this mattered in practice was a doozy, checkout aviros’s writeup at [Debugging story: The case of the garbage text generation](https://dev-discuss.pytorch.org/t/debugging-story-the-case-of-the-garbage-text-generation/1164)
- [Graph break on operators that fake tensor doesn’t support](https://github.com/pytorch/pytorch/pull/97708) - this fixes models that use nms and dynamic shapes (e.g., maskrcnn)
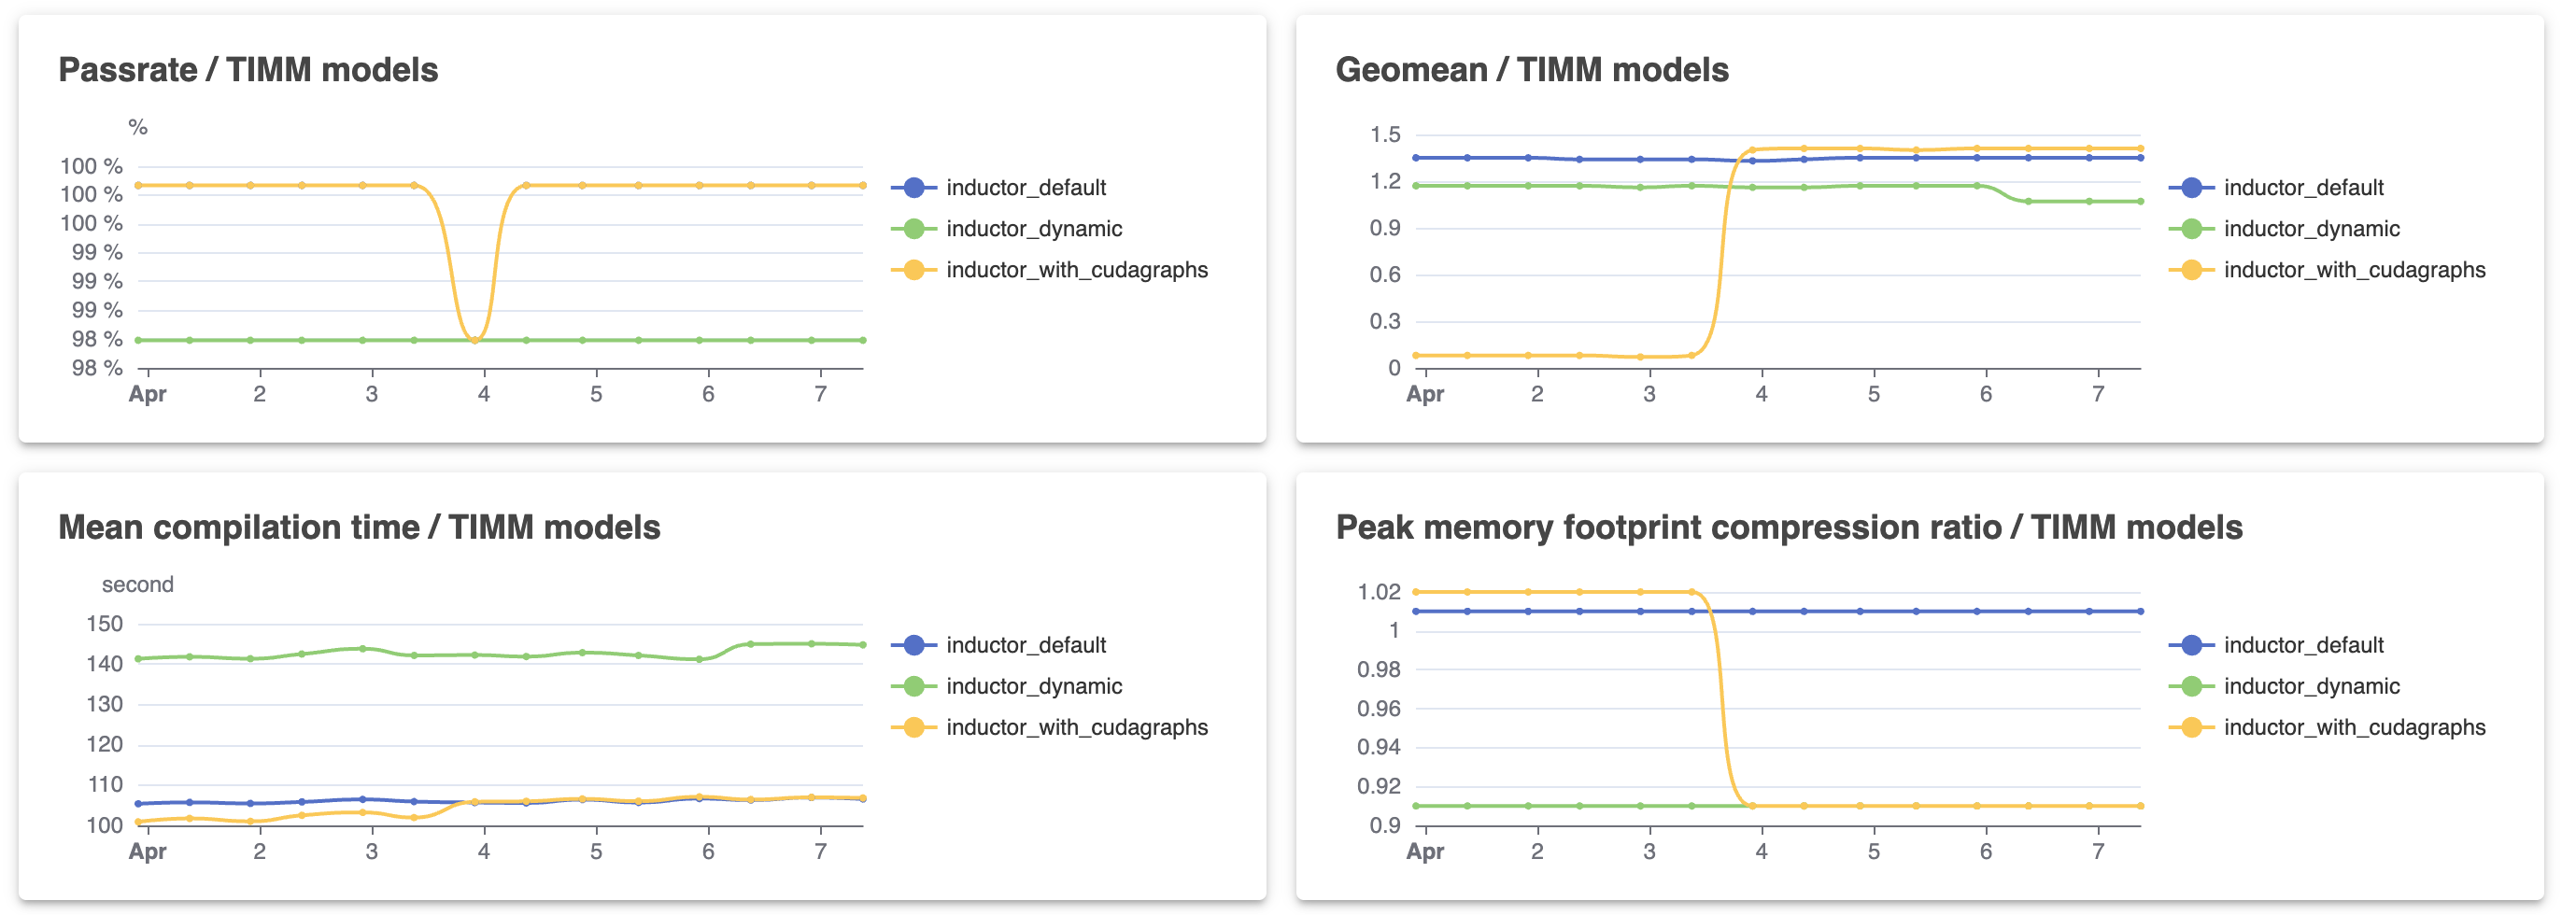
- **Dynamic shapes hits CI.** Dynamic shapes is now on the [new experimental performance dashboard](https://torchci-git-fork-huydhn-add-compilers-bench-74abf8-fbopensource.vercel.app/benchmark/compilers), thanks to the new CI-based GCP A100 infrastructure it was really easy to add a new configuration. We’re switching our weekly stats reporting to it. One thing to note: this runs dynamic shapes in a non-standard configuration where ONLY batch size is treated as dynamic. The performance and compile time is quite a bit worse if you do “YOLO everything dynamic shapes” with dynamic=True. By the way, there’s also now a [script to summarize performance from a CI performance run](https://github.com/pytorch/pytorch/pull/97977) if you want to do a one-off experiment.
- **Multi-level cache / shape env.** Voz, Natalia and I have begun discussing in earnest how exactly to setup multi-level cache and shape env. Here is our current thinking:
- _It’s not just a two-level cache._ We need the ability to use guards to switch between several possible artifacts in several situations: (1) in backwards, in case compiling the backwards graph results in more guards than were initially installed in forwards, (2) in backwards, in case the passed in gradient is not contiguous (e.g., channels last gradient) and changes the validity of the compiled backwards kernel, (3) in forwards, when compiling graphs with operators that have data-dependent output shapes. Originally, our dogma was that such operators should result in graph breaks until inductor learned how to compile them (much later in the future). However, graph breaks inside deeply inlined functions are extremely bad for performance, since if you have the call stack f1-f2-f3 and f3 graph breaks, you end up having to compile six separate graphs: f1-pre, f2-pre, f3-pre, f3-post, f2-post and f1-post. There is no opportunity to fuse among these graphs. A post-dynamo, pre-inductor notion of graph break would allow inductor to guard on the specifics of the data dependent shape, while still permitting these fusion opportunities.
- _No replacements after the first level._ A big complication with a generalized multi-stage ShapeEnv is that we have a large number of SymNodes floating around, whose saved sympy expressions automatically get updated if we discover a new replacement (e.g., mapping s0 to 3). Although there are some complicated schemes that can handle this in full generality, our current thinking is that we will restrict replacements to the first level. For later levels (e.g., in backwards), we can only add guards, we will never add new replacements. In practice, this should work well, as backward shapes match their forwards, so the only new guards will just be Inductor-level guards on alignment, etc.
- **State of real world model enablement.**
- [torchbench pin is updated](https://github.com/pytorch/pytorch/pull/98003/files), but many of the new models we were interested are failing in CI. LLaMA is failing due to missing complex32 support (see also [[Inductor] Complex multiplication fails in inductor with KeyError: torch.complex64 · Issue #97562 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/97562)); gat, gcn and sage are failing due to only supporting CPU (weird, this sounds like a misconfiguration); InstructPix2Pix is currently [stuck in canary model](https://github.com/pytorch/benchmark/pull/1451) until we fix it not to download model weights.
- [detectron2](https://github.com/pytorch/pytorch/issues/93431) - I did some initial investigation on `detectron2_fasterrcnn_r_101_c4` and noticed it is failing on translation to torch.\_assert. (cc Tugsuu)
- [An internal multimodal model (Meta only)](https://fb.workplace.com/notes/875336403560939/) is 5x slower on Azure A100 but 5x faster on devgpu A100. Weird! It also seems to infinite loop on the devgpu A100 if you remove the graph breaks. I have the go ahead from the research scientist to publish a sanitized version of the model without weights, coming soon.
The numbers:
- **Model status on master.**
- CI skips (aot\_eager inference/training; inductor inference/training): -1, -2, -7, -1 (all unchanged)
- Perf passrate (torchbench, huggingface, timm\_models): 54/63, 41/45, 61/62 (new!) (delta: -2, -3, -1)
- Geomean speedup: 1.09x, 1.28x, 1.17x (new!) (delta: -.06x, -.11x, -.18x)
- Mean compilation time: 84s, 104s, 141s (new!) (delta: +48s, +39s, +36s)
- Peak memory footprint compression ratio: 0.76x, 0.99x, 0.91x (new!) (delta: -.16x, -.05x, -.10x)
## What’s coming next?
- Voz: Multi-level cache/shape env
- Avik: Ostensibly unblocked on dynamic\_dim(…) \<= 2 constraints API
- Edward: Some CM3Leon, some understanding why things are slow
- Horace: 1. Dynamic shape minifier, 2. Some shape padding stuff, 3. Pre-autograd make\_fx
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [April 9, 2023, 1:15am UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/50 "2023-04-09T01:15:58Z")
# State of symbolic shapes: Apr 7 edition
Previous update: [State of symbolic shapes branch - #48 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/48#state-of-symbolic-shapes-apr-1-edition-1)
## Executive summary
- **T5 is fast now.** In [T5 model taking too long with torch compile. · Issue #98102 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/98102), HuggingFace was trying out torch.compile on an E2E T5 model. Their initial attempt was a 100x slower because their model was dynamic and repeatedly recompiled. After fixing a long string of issues (switch to dynamic=True, patching in their change to exclude compilation time from iter/s calculation, eliminating guards on NN parameters, reducing inductor induced recompilation), we are now 2x faster than eager mode! A great result.
- **Dashboard changes.** We changed some of the methodology of our performance runs, mostly making it stricter. In particular, we now [require sequence length in huggingface to be dynamic](https://github.com/pytorch/pytorch/pull/98335) (previously, we only marked batch dimensions as dynamic), and we now [require batch dimensions to be compiled dynamically](https://github.com/pytorch/pytorch/pull/98334) (raising an error if the batch dimension gets specialized.) These did not materially affect our pass rates, but enabling dynamic sequence length on huggingface did result in an end-to-end perf regression. We also [switched accuracy CI to dynamic batch only](https://github.com/pytorch/pytorch/pull/98307), which eliminated most of our outstanding CI failures. One potential methodology problem still in our performance runs is we do not propagate dynamic dimensions; thus, if a model has a graph break, all subsequent graphs will be compiled statically. We need to better understand the extent of this problem.
- **mark\_static.** There is now a [mark\_static](https://github.com/pytorch/pytorch/pull/98427) function, which is analogous to `torch._dynamo.mark_dynamic`, except that it forces a dimension to be compiled statically. So overall, your tools for controlling dynamism are: dynamic=True makes everything dynamic (but duck sized), mark\_static lets you force things to be static, assume\_static\_by\_default makes everything static, and mark\_dynamic lets you force things to be dynamic. Once @voz lands automatic dynamic detection on recompilation, we will switch assume\_static\_by\_default to be the default and you can either explicitly mark\_dynamic, or wait for a recompile to induce dynamism. Making everything dynamic by default would be relegated to situations where you absolutely do not want to recompile.
- **Inductor optimization ablation study.** Check out [A small inductor optimization ablation study](https://dev-discuss.pytorch.org/t/a-small-inductor-optimization-ablation-study/1181) for a better understanding of where the performance gaps between dynamic shapes and not are coming from.
- **A new strategy for inductor guards.** Last week, we proposed that in forwards, we may need to have a notion of an “inductor” graph break, which would permit inductor to install guards on otherwise dynamic values that we cannot float to the top level. While this is still necessary in principle, our new thinking is that we should rarely need it: most guards from inductor arise from optional optimizations, and what we should do is just make sure to disable these optimizations when we cannot conveniently install a guard.
- **Guard CSE.** Yukio has a PR [https://github.com/pytorch/pytorch/pull/98488](https://github.com/pytorch/pytorch/pull/98488) for running CSE at a Python-level on guards. It shows a 2-4% across the board performance improvement. Nice! There are some correctness issues that must be ironed out before landing.
- **Nested tensor metadata format change proposal.** Me, Joel, Alban and Basil worked out an alternate proposal for nested tensor metadata representation, motivated by Joel’s difficulties in modeling nested tensor contiguity with symbolic shapes, as nested tensor stores strides in a tensor, which means there is no straightforward way to actually compute if something is contiguous without something data dependent. The updated proposal has several parts: (1) nested tensor distinguishes dim=0 (the batch dimension) to be the only dimension by which jagged dimensions can vary; in other words, a nested tensor can always be modeled as a list of dense tensors; (2) after the batch dimension, there may be any number of inter-mixed dense/ragged dimensions, followed by a suffix of dense dimensions only; (3) only the suffix of dense dimension and the right-most ragged dimension can be non-contiguous; the batch and inter-mixed dense/ragged prefix MUST be contiguous; (4) this suffix has strides represented as ordinary integers without any raggedness. The general idea is to understand under what circumstances strides can be represented without hitting raggedness, and allow discontiguity on those strides ONLY. Meeting notes at [https://docs.google.com/document/d/1BFNKz1XziYbhnBo48kJ9\_DzmiwPgcXREpH3La6JCCQU/edit#](https://docs.google.com/document/d/1BFNKz1XziYbhnBo48kJ9_DzmiwPgcXREpH3La6JCCQU/edit#)
- **Notable bug fixes.**
- Less recompilations (at the cost of disabling certain optimizations): [Turn off divisible\_by\_16 for dynamic shapes](https://github.com/pytorch/pytorch/pull/98471), [Disable persistent reductions with dynamic shapes](https://github.com/pytorch/pytorch/pull/98405)
- Reduced guard overhead: [Do not track parameters, do not generate guards](https://github.com/pytorch/pytorch/pull/98350)
- Direct error fixes: [Add detect\_fake\_mode](https://github.com/pytorch/pytorch/pull/98321), [Teach requires\_bwd\_pass how to interpret int.](https://github.com/pytorch/pytorch/pull/98312), [Fix some more places where we incorrectly assume only Tensor](https://github.com/pytorch/pytorch/pull/98310)
- Logging QOL: [Only print guard code when printing guards](https://github.com/pytorch/pytorch/pull/98347), [Add more debug logs to evaluate\_expr](https://github.com/pytorch/pytorch/pull/98344) (you can take advantage of these logs with `TORCH_LOGS=guards,+torch.fx.experimental.symbolic_shapes`, definitely useful if you’re investigating overspecialization)
- **State of real world model enablement.**
- [CM3leon-760M (this is that Meta only, name is OK’ed to share)](https://fb.workplace.com/notes/875336403560939/) - OK, so it was a roller coaster this week. It turns out that this model wasn’t ever 5x faster; instead, we had missed that the units had changed from ms to s (oof!) Benchmarking with torch.profiler suggested that guard overhead was a major problem, and we shelved it for now. However, work on T5 identified a number of problems; so at the end of the week I gave CM3Leon and we now see a very slight improvement (at generate\_size=10, we go from 150ms to 131ms.) Kineto profiles suggest CPU overhead is still an issue (see below), though TBF Kineto always thinks CPU overhead is the problem (due to the fact that the profiler distorts CPU overhead.) One hope is that upcoming attention optimization by jansel should help. 
The numbers (as of 46d765c):
- **Model status on master.**
- CI skips (aot\_eager inference/training; inductor inference/training): 0, 0, -1, 0 (+1, +2, +6, +1 WoW); the improvements are primarily due to switching to dynamic batch only (in other words, the bugs still exist, but we expect realistic usage not to care about them as they result from making dimensions dynamic that don’t need to be dynamic)
- Perf passrate (torchbench, huggingface, timm\_models): 53/63, 43/45, 61/62 (-1, +2, 0 WoW) (delta: -3, -2, -1). vision\_maskrcnn
- Geomean speedup: 1.09x, 1.35x, 1.07x (0, +0.07x, -0.10x WoW) (delta: -.06x, -.04x, -.28x). Need to investigate TIMM slow down
- Mean compilation time: 81s, 97s, 145s (-3s, -7s, +4s WoW) (delta: +22s, +35s, +38s)
- Peak memory footprint compression ratio: 0.75x, 0.99x, 0.91x (-.01x, -.04x, 0 WoW) (delta: -.15x, -.02x, -.10x)


## What’s coming next?
- Voz: Autodetect dynamic on recompile
- Edward: solidifying specialization logging, fixing CI validity problems, fix backwards soundness problems
- Horace: 1. Dynamic shape minifier, 2. Some shape padding stuff, 3. Pre-autograd make\_fx
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [April 16, 2023, 2:27am UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/51 "2023-04-16T02:27:05Z")
# State of symbolic shapes: Apr 15 edition
Previous update: [State of symbolic shapes branch - #50 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/50#state-of-symbolic-shapes-apr-7-edition-1)
## Executive summary
- **Assume static by default is default.** [Automatic Dynamic Shapes by voznesenskym · Pull Request #98923 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/98923) prefigures our eventual approach for enabling dynamic by default: we assume everything is static, and then when we notice that we recompiled because a size changed, we compile with the dimension dynamic. This means dynamic=True results in more recompilations than it did before (because you will compile once static and then once dynamic), but you now you only pay (in terms of bugs and performance) for dimensions that are actually dynamic. If you want to skip the recompile, you still can use `torch._dynamo.mark_dynamic` to force a dimension to be compiled dynamically; you can also set `assume_static_by_default=False` to go back to the “YOLO everything is dynamic” flow.
- **Backward retracing is no more!** Read [https://github.com/pytorch/pytorch/pull/99089](https://github.com/pytorch/pytorch/pull/99089) for all the details, but the short version is we now share ShapeEnv between backwards and forwards, which should improve the precision of backwards graphs we compile. Unfortunately, this also regresses accuracy on yolov3, which we are investigating.
- **Large negative numbers now work with SymInt.** Previously, it wasn’t possible to pass INT\_MIN to a SymInt argument. Now you can do it with [Support large negative SymInt by ezyang · Pull Request #99157 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/99157) ; this was necessary to unblock SymInt’ifying randint and randperm.
- **Big improvements in symbolic shapes logging.** You can use `TORCH_LOGS=torch.fx.experimental.symbolic_shapes` to see logs about symbolic shapes. Importantly, we now report both the user and framework code that caused a guard to be added at INFO logging; this is extremely useful for debugging overspecialization. See [Support large negative SymInt by ezyang · Pull Request #99157 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/99157) for some sample logs.
- **Notable bug fixes.**
- [Don't specialize when indexing by SymInt by ezyang · Pull Request #99123 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/99123) - `x[symint]` no longer specializes
- [Change unspec ints to not be duck-sized by ezyang · Pull Request #99010 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/99010) - this prevents spurious specialization when you have int inputs to your graph
- [Make Tensor.\_\_contains\_\_ accept SymInt/Float/Bool. by ezyang · Pull Request #98933 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/98933) and [Add unbacked symbool support by tugsbayasgalan · Pull Request #98877 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/98877) - `x in tensor` now avoids specialization
- [Apply dynamic shapes policy correctly to \_base tensor by voznesenskym · Pull Request #99211 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/99211) - we no longer generate symbols for sizes on the \_base of a tensor, good riddance! Discovered when inspecting the new logs
- [Re-PR of 90269 - Force all nn\_module associated tensors to be static by voznesenskym · Pull Request #99108 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/99108) - buffers are now assumed to be static by default
- [Add Symbool support in python to C++ translation by tugsbayasgalan · Pull Request #98453 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/98453) - SymBool was missing a bunch of infra, now it’s nearly at parity with SymInt/SymFloat
- **State of real world enablement.** No updates, was basically all infra this week.
The nubmers (as of 1adb6fa)
- **Model status on master.**
- **CI skips:** 0, 0, -1, -1 (0, 0, 0, -1 WoW); the regression is yolov3 from the elimination of backward retracing.
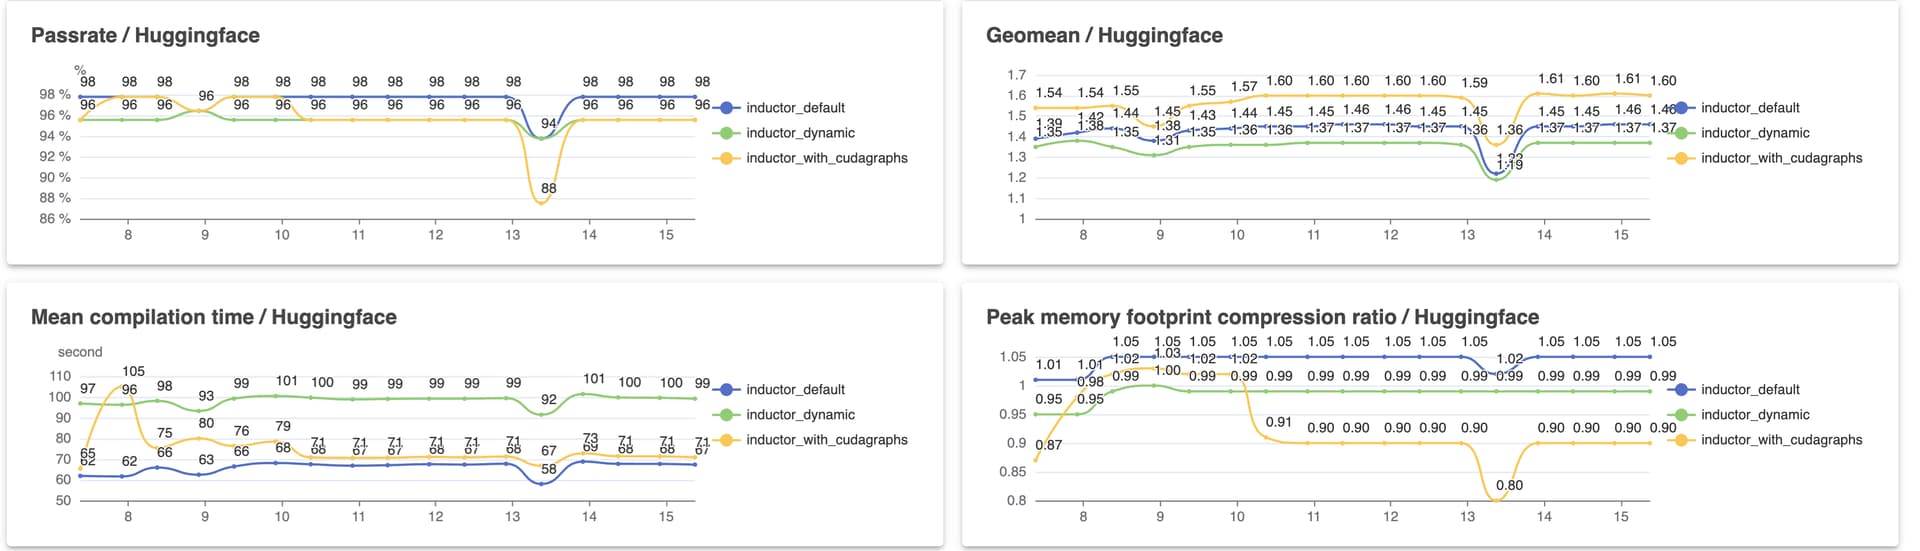
- **Perf passrate:** 88%, 53/60 → 90%, 54/60; 96%, 43/45; 98%, 61/62
- **Geomean speedup:** 1.09x → 1.12x, 1.35x → 1.37x, 1.07x → 1.08x
- **Mean compilation time:** 81s → 83s 🔺, 97s → 99s 🔺, 145s → 146s 🔺 (this seems to have affected all models though)
- **Peak memory footprint compression ratio:** 0.75x → 0.77x, 0.95x → 0.99x, 0.91x



## What’s coming next?
- Voz: dynamic on by default for real, via guard efficiency improvement
- Edward: figure out yolov3, probably by fixing the minifier
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [April 23, 2023, 7:30pm UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/52 "2023-04-23T19:30:16Z")
Status update this week is delayed on account of compiler HUD being down.
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [April 25, 2023, 2:22pm UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/53 "2023-04-25T14:22:53Z")
# State of symbolic shapes: Apr 25 edition
Previous update: [State of symbolic shapes branch - #50 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/50#state-of-symbolic-shapes-apr-15-edition-1)
## Executive summary
- **Whoops, we were measuring the wrong thing.** Big kudos to @ngimel, who noticed that when running the performance benchmarking script, we were generating entirely static kernels, even when running `--dynamic-shapes`. It turns out that our `mark_dynamic` tags were getting lost before actually making it to torch.compile region; combined with `assume_static_by_default`, this meant that we were compiling everything with static shapes–our performance difference was solely attributable to us disabling certain optimizations when `dynamic_shapes` configuration was true. We fixed this on Apr 23 with [Preserve mark\_dynamic when cloning inputs](https://github.com/pytorch/pytorch/pull/99617) (with Huggingface getting a further fix on Apr 25), which ended up wiping out some of our perf gains earlier this week (which were mostly a function of making things perform well if everything actually was static) as well as our compile time improvements from last week (ouch!) To prevent this from happening in the future, we plan to also count the number of symbols in compiled subgraphs and track this number in performance CI.
- **Assume static by default follow ups.** We broke some folks when we turned on assume static by default. [Re-enable dynamic shapes test in dynamo benchmark](https://github.com/pytorch/pytorch/pull/99816) and [Do not assume static by default when exporting (#99554)](https://github.com/pytorch/pytorch/pull/99876) helped solve some issues; we also intend to change torch.compile(dynamic=True) to force us NOT to assume static by default (pending at [#99469](https://github.com/pytorch/pytorch/pull/99469)).
- **Accuracy repro extraction/minifier.** A lot of the remaining pass rate issues are due to accuracy problems, so Edward has pivoted to working on the accuracy repro extraction and minifier to help us make progress debugging these issues. A general overview of our approach is at [Improving accuracy repro extraction - Google Docs](https://docs.google.com/document/d/1rgw5-LSUSWUCx08bwmoji_sQSHY4XNL-ogWGfB489vw/edit#) . We have a soon to land stack at [https://github.com/pytorch/pytorch/pull/99834](https://github.com/pytorch/pytorch/pull/99834) which adds the ability to serialize real data to accuracy minifier (instead of regenerating random data in the repro), and also provides the ability to perform a fast, bit-exact checksum on data (which is useful for detecting, e.g., nondeterminism.)
- As part of the minifier work, we took the BC-breaking change of [switching the backend calling convention back to real tensors](https://github.com/pytorch/pytorch/pull/99320). This means that if you are a direct Dynamo backend (as opposed to living behind AOTAutograd), you will now get real tensors from Dynamo. To fakeify them, `detect_fake_mode` and then reconvert them from fake tensor.
- **TORCH\_LOGS=dynamic.** You can now conveniently get dynamic shapes logs without typing torch.fx.experimental.symbolic\_shapes thanks to [rename sym\_shapes logger to dynamic](https://github.com/pytorch/pytorch/pull/99335)
- **Notable bug fixes.**
- [Properly parenthesize dynamo\_dynamic\_indices test](https://github.com/pytorch/pytorch/pull/99823)
- [Propagate mark\_dynamic in Dynamo compiled outputs.](https://github.com/pytorch/pytorch/pull/99634)
- [Reuse tracing context and fake tensors from backwards in forwards](https://github.com/pytorch/pytorch/pull/99619) - this fixed yolov3 accuracy failure
- [Reset joint graph fake mode earlier, and more comprehensively](https://github.com/pytorch/pytorch/pull/99391)
- [Fix isinstance on SymInt in dynamo](https://github.com/pytorch/pytorch/pull/99393)
- [Don’t detach to create parameters in MetaConverter](https://github.com/pytorch/pytorch/pull/99618)
- **Notable perf improvements.**
- A bunch of work on selectively reenabling dynamic-unfriendly optimizations if all the shapes involved are static. [div16 changes for dyn shapes](https://github.com/pytorch/pytorch/pull/99930) [Allow persistent reductions in dynamic shapes if last numel is static](https://github.com/pytorch/pytorch/pull/99789) [Allow split\_reduction if all dyn values are static](https://github.com/pytorch/pytorch/pull/99475)
- [Guard static shapes alongside tensors, instead of from shape\_env, in dynamic\_shapes=True](https://github.com/pytorch/pytorch/pull/99566) - 2-3% geomean speedup, though the real improvement may be less now that we have more dynamic shapes in perf runs
**CI skips.** 0, 0, 0, -2 (0, 0, +1, -1 WoW); yolov3 is fixed; levit\_128 is an accuracy failure that only happens on A10G, interestingly, it is already skipped on aot\_eager (but not inductor). sebotnet33ts\_256 is flaky.
**The dashboard (as of 466adab).** [The week on HUD.](http://hud.pytorch.org/benchmark/compilers?startTime=Tue%2C%2011%20Apr%202023%2013%3A20%3A04%20GMT&stopTime=Tue%2C%2025%20Apr%202023%2013%3A20%3A04%20GMT&suite=torchbench&mode=training&dtype=amp&lBranch=main&lCommit=466adab7c4bea54fd6610ead7f5cd584dea58d2a&rBranch=main&rCommit=1adb6fa92248cb52f36f6c8efcd2df1520cd6155)
As mentioned previously, the results this week regressed because we fixed a methodology problem in the benchmark suite (where we weren’t actually generating dynamic kernels). In general, our pass rate was not affected too much, but we lost most of our performance improvements from mid week (which makes sense, because these improvements were mostly “if everything actually is static, do the fast static path”–clearly these improvements would be overrepresented if everything was static!) The other important thing to note is that we turned off dynamic sequence lengths on Huggingface (as it did not work for most models; see the dip on the 23rd); we will work to turn this back on, which should result in another regression next week.
Here are the top line metric changes from this week:
| Metric | Torchbench | Huggingface | TIMM models |
| --- | --- | --- | --- |
| Passrate | 90%, 54/60 → 86%, 51/59 🔻 | 96%, 43/45 → 97%, 32/33 | 98%, 61/62 |
| Speedup | 1.12x → 1.07x 🔻 | 1.37x → 1.32x 🔻 | 1.08x → 1.03x |
| Comptime | 83s → 87s 🔺 | 99s → 114s 🔺 | 146s → 132s |
| Memory | 0.77x → 0.86x | 0.99x → 1.05x | 0.91x → 1.01x |


This month on HUD. It’s been a month since we’ve enabled the GCP A100 runners for performance testing, so I’ve also included the month long graphs for dynamic shapes only. Some important dates in the graphs: on Mar 29 we switched from trying to make everything dynamic, to making everything static (remember; at the time, we thought we were keeping batch size dynamic, but actually we were wrong), and on Apr 24 (the very last data point), we fixed it to actually have dynamic batch size.


## What’s coming next?
- Voz: dynamic on by default for real at [[Experiment] Enable dynamic shapes on by default](https://github.com/pytorch/pytorch/pull/99801)
- Edward: follow through on minifier, or work on some model enablement, or work on reducing log spew
- Horace: talking to folks to figure out orientation of dynamic shapes to LLMs. Overhead reduction is one big theme so far.
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [May 1, 2023, 2:26pm UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/54 "2023-05-01T14:26:11Z")
Skipping this week’s update, as the GCP benchmark runners are currently broken.
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [May 6, 2023, 7:24pm UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/55 "2023-05-06T19:24:02Z")
# State of symbolic shapes: May 6 edition
Previous update: [State of symbolic shapes branch - #52 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/52#state-of-symbolic-shapes-apr-25-edition-1)
## Executive summary
- **Big grind for dynamic by default.** @voz reports that enabling dynamic by default (or, more specifically, static by default but automatically turn on dynamic on recompile) has turned into a bit of a slog. Some of the reasons: (1) people have been adding new test files to the Dynamo test suite, but those tests have not been simultaneously run with dynamic shapes so we were running blind there, (2) it’s not risk free to recompile into dynamic shapes (our plan to derisk here is to remove dynamic\_shapes=True but keep automatic dynamic false to start) and in practice some things broke on the full PyTorch test suite + dynamo, (3) there a lot of conditionals on `dynamic_shapes` scattered throughout the codebase and they all have to be rewritten not to do this.
- **Accuracy work on dynamic shapes should be unblocked by improved accuracy minifier.** We’ve fixed one bug with the help of the new minifier infra described at [Major updates to the after AOT accuracy minifier!](https://dev-discuss.pytorch.org/t/major-updates-to-the-after-aot-accuracy-minifier/1241) ; hopefully we can nail more!
- **Notable bug fixes.**
- [[inductor] Prevent reusing aliased buffers if aliases still have uses](https://github.com/pytorch/pytorch/pull/100332). This caused the old
- [More rigorous mixed overloads on SymInt](https://github.com/pytorch/pytorch/pull/100008)
**CI skips.** 0, 0, 0, -2 (no change WoW). We’re planning to use the improved accuracy minifier tools to nail the accuracy failures.
**The dashboard (as of 675029a).** [This week on HUD.](http://hud.pytorch.org/benchmark/compilers?startTime=Sat%2C%2022%20Apr%202023%2018%3A01%3A03%20GMT&stopTime=Sat%2C%2006%20May%202023%2018%3A01%3A03%20GMT&suite=torchbench&mode=training&dtype=amp&lBranch=main&lCommit=675029aabf143a60aee62c21e093ed1091f46743&rBranch=main&rCommit=466adab7c4bea54fd6610ead7f5cd584dea58d2a)
Here are the top line metric changes from this week:
| Metric | Torchbench | Huggingface | TIMM models |
| --- | --- | --- | --- |
| Passrate | 86%, 51/59 → 85%, 50/59 🔻 | 98%, 44/45 | 98%, 61/62 → 100%, 62/62 |
| Speedup | 1.07x → 1.09x | 1.40x → 1.41x | 1.03x → 1.08x |
| Comptime | 87s → 84s | 111s → 110s | 132s → 133s 🔺 |
| Memory | 0.86x | 1.06x | 1.01x |
The graphs suggest it was a bit of a roller coaster week:
- There’s a big regression for torchbench and timm on the 26th, for dynamic shapes only. It is probably due to [https://github.com/pytorch/pytorch/pull/99383](https://github.com/pytorch/pytorch/pull/99383), but there was a big improvement on torchbench yesterday, due to [[dynamo] Hide guard\_fail\_hook behind a flag to improve cache lookup time (+10% DebertaV2) by anijain2305 · Pull Request #100590 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/100590)
- In timm, there was a major improvement from [div16 changes for dyn shapes by voznesenskym · Pull Request #99930 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/99930)
- The passrate regression on torchbench is being tracked at [hf\_LongFormer failing eval with inductor and dynamic shapes · Issue #100812 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/100812)


## What’s coming next?
- Voz: still grinding on dynamic by default, also moonlighting on improving Deberta performance
- Edward: nail some accuracy bugs, think about de-TensorImpl’ification or partial CUDA graphs application, maybe help on HF
- Horace: optimizing distributed collectives
- Joel: jagged tensor in inductor
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [May 14, 2023, 4:58pm UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/56 "2023-05-14T16:58:14Z")
# State of symbolic shapes: May 14 edition
Previous update: [State of symbolic shapes branch - #54 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/54#state-of-symbolic-shapes-may-6-edition-1)
## Executive summary
- **New benchmarks.** Edward’s focus on this week was adding new benchmarks. We now have autoregressive generation benchmarks (hf\_T5\_generate, cm3leon\_generate, llama is now enabled in our benchmark suite, and coming soon are some new GNN benchmarks as well as working vision\_maskrcnn (having solved its eager mode determinism problems.) This finally makes good on our promise last month to add a dynamic-shapes oriented set of benchmarks for more fine-grained tracking. Once these benchmarks stabilize we will report for these models specifically in our updates. What’s still missing? We’d also like to get detectron2 working, and it would be good to have llama\_generate and gpt2\_generate (broken due to HF bug.) There’s also not much representation from generative image models at the moment. We also want to be tracking [HuggingFace’s compile experiments](https://github.com/younesbelkada/hf-torch-compile-benchmark) closely. The new benchmarks are also quite broken with torch.compile, more bug fixing required!
- **Translation validation.** Yukio has posted an initial [translation validator](https://github.com/pytorch/pytorch/pull/101146) for our symbolic shape reasoning. How exciting!
- **Hint sets.** One hypothesis we have about the perf regression from [State of symbolic shapes branch - #54 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/54#state-of-symbolic-shapes-may-6-edition-1) is that we are nixing optional optimizations that, actually in practice, would be OK to apply. (A simple example is 32-bit indexing, though Natalia tells us that this one is unlikely to matter.) If this is true, we could potentially allow for more optimizations by allowing for hint sets: rather than having only one hint when inductor compiles a graph, we maintain a hint for EVERY concrete instantiation of the size vars we have seen so far. Optional optimizations that generalize to all instantiations continue to be allowed. No one is working on this yet, and we don’t know how much it will buy.
- **Towards more determinism.** Check out this post [A pure Python implementation of roi\_align that looks just like its CUDA kernel](https://dev-discuss.pytorch.org/t/a-pure-python-implementation-of-roi-align-that-looks-just-like-its-cuda-kernel/1266) which discusses how we got vision\_maskrcnn passing the eager bitwise determinism check.
- **Notable bug fixes.**
- [Turn on anomaly detection for AOTAutograd backward tracing](https://github.com/pytorch/pytorch/pull/101047) - We used this to diagnose a production bug regarding an operator with a data-dependent backwards implementation.
- [Rewrite frame state to use a struct for shapes, splitting scalar and size, prep for stride](https://github.com/pytorch/pytorch/pull/101250) - This showed up in prod!
- [Apply static policy correctly to unspec](https://github.com/pytorch/pytorch/pull/98983) - long overdue to land
**CI skips.** -2, -1, 0, -2 (-2, -1, 0, 0 WoW). The new failures are from new models (cm3leon\_generate, hf\_T5\_generate and llama) which we’ve enabled in torchbench.
**The dashboard (as of e406125).** This week on HUD.
| Metric | Torchbench | Huggingface | TIMM models |
| --- | --- | --- | --- |
| Passrate | 85%, 50/59 → 90%, 53/59 | 98%, 44/45 | 100%, 61/61 |
| Speedup | 1.09x | 1.41x → 1.39x 🔻 | 1.08x → 1.15x |
| Comptime | 84s → 90s 🔺 | 110s → 118s 🔺 | 133s → 134s 🔺 |
| Memory | 0.86x → 0.87x | 1.06x → 1.00x 🔻 | 1.01x → 0.97x 🔻 |
Some of this is just movement over all models in torchbench. However, in dynamic shapes specifically:
- torchbench dynamic only pass rate improvement on the 10th is hf\_BigBird, is likely due to Voz’s [Apply static policy correctly to unspec by voznesenskym · Pull Request #98983 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/98983) (this may also be responsible for the memory compression improvement)
- The bump on TIMM performance is likely due to the update to the TIMM commit [update timm commit by ngimel · Pull Request #100931 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/100931) though there is no obvious reason why performance improved again on the 13th.


## What’s coming next?
- Voz: dynamic by default
- Edward: Fix bugs until I die, probably fix the minifier again
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [May 21, 2023, 3:08am UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/57 "2023-05-21T03:08:59Z")
# State of symbolic shapes: May 20 edition
Previous update: [State of symbolic shapes branch - #55 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/55#state-of-symbolic-shapes-may-14-edition-1)
## Executive summary
- **PT Compiler/Distributed offsite.** PyTorch compiler and distributed had an offsite! Here’s a summary of what went down: [https://docs.google.com/document/d/1hYZJx0-y-UOvA3Ulg4kdjRXAuoWEwvNCuffvYd3Yeno/edit?usp=sharing](https://docs.google.com/document/d/1hYZJx0-y-UOvA3Ulg4kdjRXAuoWEwvNCuffvYd3Yeno/edit?usp=sharing) (Meta only). The short version is we’re going to try harder to trace eager FSDP with the PT2 stack, and that this is very, very complicated.
- **GNN victory.** puririshi98 reports 20% end-to-end speedup on [pyg\_nvfuser\_work/gcn\_neighborloader\_example.py at main · puririshi98/pyg\_nvfuser\_work · GitHub](https://github.com/puririshi98/pyg_nvfuser_work/blob/main/gcn_neighborloader_example.py), made possible with dynamic shapes, which is a great improvement from his [initial report](https://github.com/pytorch/pytorch/issues/94640) that eager was faster than compile. Nice work all!
- **Notable bug fixes.** I mostly focused on clearing dynamic shapes related user issues. I wasn’t able to fix very many before traveling to the offsite.
- [SymIntify convNd and conv\_transposeNd, fix inductor symint handling](https://github.com/pytorch/pytorch/pull/101488)
- [SymIntify functorch vmap](https://github.com/pytorch/pytorch/pull/101409)
**CI skips.** -2, -1, 0, -2 (no change).
**The dashboard (as of 03de158).**[This week on HUD](http://hud.pytorch.org/benchmark/compilers?startTime=Sat%2C%2006%20May%202023%2022%3A53%3A10%20GMT&stopTime=Sat%2C%2020%20May%202023%2022%3A53%3A10%20GMT&suite=torchbench&mode=training&dtype=amp&lBranch=main&lCommit=03de15806e5d27ee4ef6d82dbcc66dac78f6e3bf&rBranch=main&rCommit=e406125b6b411c1595c5af02a726fa46c7af5202)
| Metric | Torchbench | Huggingface | TIMM models |
| --- | --- | --- | --- |
| Passrate | 90%, 53/59 → 88%, 56/64 🔻 | 98%, 44/45 | 100%, 61/61 |
| Speedup | 1.09x → 1.12x | 1.39x → 1.48x | 1.15x → 1.17x |
| Comptime | 90s → 79s | 118s → 100s | 134s |
| Memory | 0.87x → 0.93x | 1.00x → 0.97x 🔻 | 0.97x → 1.01x |
Notes:
- torchbench pass rate change:
- basic\_gnn\_{edgecnn,gcn,gin,sage} are newly added models which pass out of the box
- vision\_maskrcnn was removed from the skip list now that its [eager mode is deterministic](https://github.com/pytorch/pytorch/pull/101116), but it still not working with dynamic shapes, needs more work
- hf\_LongFormer now failing because [hf\_LongFormer incorrect strides in copy decomp](https://github.com/pytorch/pytorch/pull/100115) was reverted
- llama now failing because [locality reordering in training](https://github.com/pytorch/pytorch/pull/101423) was disabled (it’s not clear why this affects llama though)
- moco passes because [Save global torch state to restore on graph break](https://github.com/pytorch/pytorch/pull/101201) (but perf is still not working, see [Moco failure `TypeError: can't assign a SymInt to a torch.cuda.LongTensor` · Issue #101939 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/101939))
- geomean change
- Improvements in torchbench and timm\_models (e.g., alexnet, squeezenet1\_1 from torchbench) stem from models with previously horrible performance, no longer having horrible performance. Based on discussion with @ngimel, [https://github.com/pytorch/pytorch/pull/101602](https://github.com/pytorch/pytorch/pull/101602) is likely the reason, as static shapes is incorrectly eliding indexing bound device asserts, but dynamic shapes is not eliding them and they are killing performance. These disproportionately affect image models since those models use upsamplingwhich involve indirect indexing.
- Improvements in huggingface (e.g., DebertaV2 variants) is due to [https://github.com/pytorch/pytorch/pull/99483](https://github.com/pytorch/pytorch/pull/99483)


## What’s next?
- Voz: dynamic by default is ready to land!
- Edward: OSS oncall, probably some FSDP tracing stuff
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [June 3, 2023, 8:21pm UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/58 "2023-06-03T20:21:48Z")
# State of symbolic shapes: Jun 3 edition
Previous update: [State of symbolic shapes branch - #56 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/56#state-of-symbolic-shapes-may-20-edition-1)
## Executive summary
- This update covers two weeks, on account of memorial day holiday, and also most of the dynamic shapes crew was working on FSDP tracing.
- **PT Core Libraries offsite.** PyTorch Core Libraries had an offsite. The big dynamic shapes relevant conversation we had was with @jbschlosser on nested tensor support in PT2. There will be an announce post coming soon about this working E2E; now we need to roll our sleeves up and put it into core PyTorch. One big resolution from our discussion was that it is not necessary to model jagged dimensions in our lowering stack: while having a jagged dimension, e.g., `(B, H, W)` where height and width can vary, is intuitive for end users, during lowering it is acceptable to lower this as an ordinary 1D dense tensor `(BHW,)` which contains a bunch of extra metadata that says how to reconstruct the other metadata. This is because our passes like autograd/etc do not care about the jagged structure of the tensor. Additionally, one theme was a lot of PyTorch library developers really liked doing development now in PT2, so there is a lot of interest in improving the “I want to add a new feature to PT, and I will use PT2 so I don’t have to write a CUDA kernel.” Dynamic shapes is pretty essential for kernel writers!
- **Drowning in bugs.** Two broken models that are not in the benchmark suite which I’ve been eyeballing: [Fine-tuning HuggingFace wav2vec 2.0 with `torch.compile` · Issue #101160 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/101160) (this one is broken in a lot of non-dynamic shape related ways) and [[torch.compile] Name 'Ne' is not defined (Stable Diffusion) · Issue #101228 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/101228) (there a bunch of potential small changes which can fix it)
- **A reach out from FT users.** Some folks using FT to do LLM inference are interested in what the long term state of dynamic shapes and PT2 will be; will PT2 be a viable alternative to FT? Today, our gap with FT is moderately significant, esp because we cannot use CUDA graphs with dynamic shapes. However, we hope that (1) with things like kvcache, you do not actually need dynamic shapes and (2) continual improvements to PT2, we will be a competitive and much more user friendly alternative to FT. Hopefully with our increasing focus on LLMs (thanks @drisspg and the rest of the blueberries folks) we should continue to make progress on this front.
- **Notable new issues.**
- [Dynamo should only unroll loops by a preset factor (unless otherwise explicitly instructed) · Issue #102839 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/102839) - Now that we’re running torch.compile on end-to-end autoregressive generation this is showing up, esp with nanogpt\_generate (which is simple enough that there are no graph breaks). Driss volunteered to look into it.
- [mark\_dynamic may error too aggressively · Issue #102814 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/102814) - mark\_dynamic is kind of hard to use. Stopgap may be to have variant that doesn’t error if it fails to be dynamic.
- **Notable bug fixes.**
- [Improve repeat\_interleave with scalar repeat value](https://github.com/pytorch/pytorch/pull/102570) by peterbell10; we no longer specialize if you call repeat\_interleave
- [Graph break on differentiable boolean mask setitem](https://github.com/pytorch/pytorch/pull/102843)
- [RelaxUnspecConstraint some mor](https://github.com/pytorch/pytorch/pull/102729) - this makes mark\_dynamic no longer complain if you mark a 0/1 size dim dynamic (it will specialize, but no big deal)
**CI skips.** -1, -1, -1, -2 (+1, 0, -1, 0). hf\_T5\_generate and cm3leon\_generate are now passing (though hf\_T5\_generate [in a somewhat hacky way](https://github.com/pytorch/pytorch/issues/102814)). New failure is nanogpt\_generate which was previously failing even in static, new work item for us.
**The dashboard (as of 8215468870).** [This fortnight on HUD](https://hud.pytorch.org/benchmark/compilers?startTime=Thu%2C%2004%20May%202023%2018%3A54%3A50%20GMT&stopTime=Sat%2C%2003%20Jun%202023%2018%3A54%3A50%20GMT&granularity=day&suite=torchbench&mode=training&dtype=amp&lBranch=main&lCommit=8215468870daae5a1da7ac02f98f4e2ddf2d7623&rBranch=main&rCommit=03de15806e5d27ee4ef6d82dbcc66dac78f6e3bf)
There is a discontinuity in speedup, due to a change in how we count speedup: we now (1) clamp model speeds to 1x (previously, a PT2 caused slowdown could depress overall speedup; this was the case for torchbench was revised from 1.12 to 1.15), and (2) we now include models that fail accuracy in geomean speedup as 1x (this depresses the geomean speedup, e.g., HuggingFace was revised from 1.48 to 1.45).
| Metric | Torchbench | Huggingface | TIMM models |
| --- | --- | --- | --- |
| Passrate | 88%, 56/64 | 98%, 44/45 | 100%, 60/60 |
| Speedup | 1.15x → 1.16x | 1.45x → 1.53x | 1.20x → 1.22x |
| Comptime | 79s | 100s → 103s 🔺 | 134s → 135s 🔺 |
| Memory | 0.93x → 0.94x | 0.97x → 1.00x | 1.01x |
Notes:
- HuggingFace and torchbench improvements are due to several broad base optimizations that affected all configurations; these include [inductor: eliminate meaningless copy](https://github.com/pytorch/pytorch/pull/102089) and [squash xblock for persistent inner reduction](https://github.com/pytorch/pytorch/pull/102444) (this one disproportionately affects transformer models and accounts for all of the torchbench improvement).
- 2% TIMM models geomean increase is attributable to a big improvement in lcnet\_050. It is not entirely clear which PR booked this win but my guess is [the Triton pin update](https://github.com/pytorch/pytorch/pull/101919).
- There is a huge performance for TIMM models win landed via convolution layout optimization, [but it is disabled for dynamic shapes](https://github.com/pytorch/pytorch/pull/99773#issuecomment-1575157257), so we didn’t see any benefit from it.
I probably ought to report inference numbers too but they are only being run twice a week and our latest set of improvements are not in an official benchmark run.


## What’s next?
- Voz: working on tracing FSDP
- Edward: fixing bugs
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [June 11, 2023, 2:46am UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/59 "2023-06-11T02:46:57Z")
# State of symbolic shapes: Jun 10 edition
Previous update: [State of symbolic shapes branch - #57 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/57#state-of-symbolic-shapes-jun-3-edition-1)
## Executive summary
- **Update on dynamic shapes by default.** Voz has handed off this workstream to me. Here is what you need to know:
- **Staged roll out.** Consider three relevant config variables: `dynamic_shapes` (is dynamic shapes enabled at all), `automatic_dynamic_shapes` and `assume_static_by_default` (do we assume everything is static or dynamic by default). Prior to this week, the default settings for these variables were `dynamic_shapes = False`, `automatic_dynamic_shapes = False` (updated to this recently), `assume_static_by_default = True`. Phase 1: `dynamic_shapes = True` (but note that this should be NO substantive behavior change, since we assume static by default, and don’t automatically promote to dynamic on recompilation.) Phase 2: `automatic_dynamic_shapes = True`.
- **State of Phase 1.** Our strategy is to incrementally remove all explicit tests on `dynamic_shapes` in the codebase, at which point switching to `dynamic_shapes = True` is trivial. This spreadsheet tracks all remaining use sites: [Dynamic shapes by default tracker - Google Sheets](https://docs.google.com/spreadsheets/d/1vIvFLWEohwQXLFZtQLbO1UAQFsfTj9WXEspAhvRZcLw/edit#gid=0) The biggest cluster of failures involve side effects from allocating a ShapeEnv (even if it is unused); the most complicated failures regard indexing strength reduction and layout optimization in inductor.
- **State of Phase 2.** Voz gamed out what test suite changes would be necessary in [https://github.com/pytorch/pytorch/pull/100815](https://github.com/pytorch/pytorch/pull/100815) . A lot of the brittleness is from tests that assume that running with different sizes would induce a recompile (which may no longer happen if you hit the symbolic case.) This part is still a bit murky. Hopefully the hardening work we’ve been doing will help make this smooth.
- **We fixed dynamic=True to not assume static by default.** This regressed a while ago and we’ve finally gotten around to reverting the behavior back. If you say `torch.compile(dynamic=True)` this means “YOLO make everything dynamic.” To only make things dynamic if they actually vary, instead set the configs `dynamic_shapes=True; automatic_dynamic_shapes=True` (this is no longer controlled by `dynamic=True` as we intend to make this behavior default).
- **PT2 internal customers brainstorm.** It’s roadmapping season. Dynamic shapes was a recurrent theme for our internal use cases, as dynamic shapes recompilation and jagged tensor are key gaps in our PT2 support. Edward asked to follow up on how comprehensive our per-operator dynamic shapes support is (when do we specialize?) and improve our logging to better identify when recompilation happens. In fact, we already have logs for recompilation, but they are useless because they are attributed to dynamically generated Python code from FX codes; need better provenance.
- **Model enablement.**
- lit-llama: I’m slowly working on adding it to torchbench (this is really stress testing our benchmark infrastructure, as some of the reported bugs involve the fine-tuning training recipes which isn’t really something that our current benchmark runner knows how to do. The PoR is to have separate lit\_llama, lit\_llama\_lora, lit\_llama\_generate). This model triggers a lot of bugs.
- Wav2Vec2: This has some sort of AOTAutograd problem, I’m also close to adding it to the huggingface benchmark suite, was blocked on deepcopy not working on the model which is fixed by [Add parametrization version of weight\_norm](https://github.com/pytorch/pytorch/pull/103001)
- **Notable bug fixes.**
- [Properly respect automatic dynamic config for unspec int](https://github.com/pytorch/pytorch/pull/103321)
- [Teach Triton codegen to generate sqrt](https://github.com/pytorch/pytorch/pull/103084)
- [Fix graph break on boolean mask better](https://github.com/pytorch/pytorch/pull/103052)
- **Notable new issues.**
- [torch.compile(model.generate) cannot run under torch.inference\_mode() with dynamic input shape](https://github.com/pytorch/pytorch/issues/103132) - bdhirsh has fix pending
- [lit-llama lora fine tuning NetworkXUnbounded: Infinite capacity path, flow unbounded above](https://github.com/pytorch/pytorch/issues/103055)
- [AttributeError when attempting to remove inductor buffers twice](https://github.com/pytorch/pytorch/issues/102857) - has fix, just needs to be submitted
**CI skips.** -1, -1, -1, -2 (no change.)
**Training dashboard (as of daf75c0759).**[This week on HUD](https://hud.pytorch.org/benchmark/compilers?startTime=Sun%2C%2028%20May%202023%2002%3A17%3A45%20GMT&stopTime=Sun%2C%2011%20Jun%202023%2002%3A17%3A45%20GMT&granularity=hour&suite=torchbench&mode=training&dtype=amp&lBranch=main&lCommit=daf75c07593aafc321efd652e773dd3823126743&rBranch=main&rCommit=8215468870daae5a1da7ac02f98f4e2ddf2d7623)
| Metric | Torchbench | Huggingface | TIMM models |
| --- | --- | --- | --- |
| Passrate | 88%, 56/64 → 89%, 56/63 | 98%, 44/45 | 100%, 60/60 |
| Speedup | 1.13x | 1.58x → 1.59x | 1.19x → 1.18x |
| Comptime | 79s | 103s | 135s → 136s |
| Memory | 0.94x → 0.93x | 1.00x | 1.01x |
A quiet week.
- Passrate denominator went down as llama is now correctly excluded from training (our llama implementation is un-trainable.)
- Speedup fluctuations look like noise (no individual model with more than 5% change)


**Inference dashboard (as of daf75c0759, comparing with 7c2641d5f1).** [This week on HUD](https://hud.pytorch.org/benchmark/compilers?startTime=Sun%2C%2028%20May%202023%2002%3A17%3A45%20GMT&stopTime=Sun%2C%2011%20Jun%202023%2002%3A17%3A45%20GMT&granularity=hour&suite=torchbench&mode=inference&dtype=amp&lBranch=main&lCommit=daf75c07593aafc321efd652e773dd3823126743&rBranch=main&rCommit=7c2641d5f1081811e664267406df1059687aad7a)
| Metric | Torchbench | Huggingface | TIMM models |
| --- | --- | --- | --- |
| Passrate | 85%, 63/74 → 86%, 64/74 | 100%, 45/45 | 100%, 60/60 |
| Speedup | 1.31x → 1.37x | 1.45x → 1.94x | 1.36x → 1.43x |
| Comptime | 23s → 27s | 36s → 42s | 36s → 41s |
| Memory | 1.10x → 1.14x | 1.24x → 1.60x | 1.16x → 1.06x |
This is more like a two week range, because last week the granularity of inference run was very coarse (we are now running inference daily, thanks Bin.)
- Passrate is a two steps forward, one step back deal. cm3leon\_generate and hf\_Bart succeeding; doctr\_reco\_predictor now failing (this model is failing for all configs, not just dynamic.)
- Perf improvement is due to an across the board improvement. Frustratingly, I have no idea which PR the improvement is for! The suspect range is 07104ca99c9d297975270fb58fda786e60b49b38..49450fe021cc5d439f56580463461ff438f9ac96 (which, perhaps not so coincidentally, is the same range that doctr\_reco\_predictor started failing.) UPDATE: This is because we turned on AMP for inference, whereas previously everything was in float32. Mystery solved! Thanks @eellison

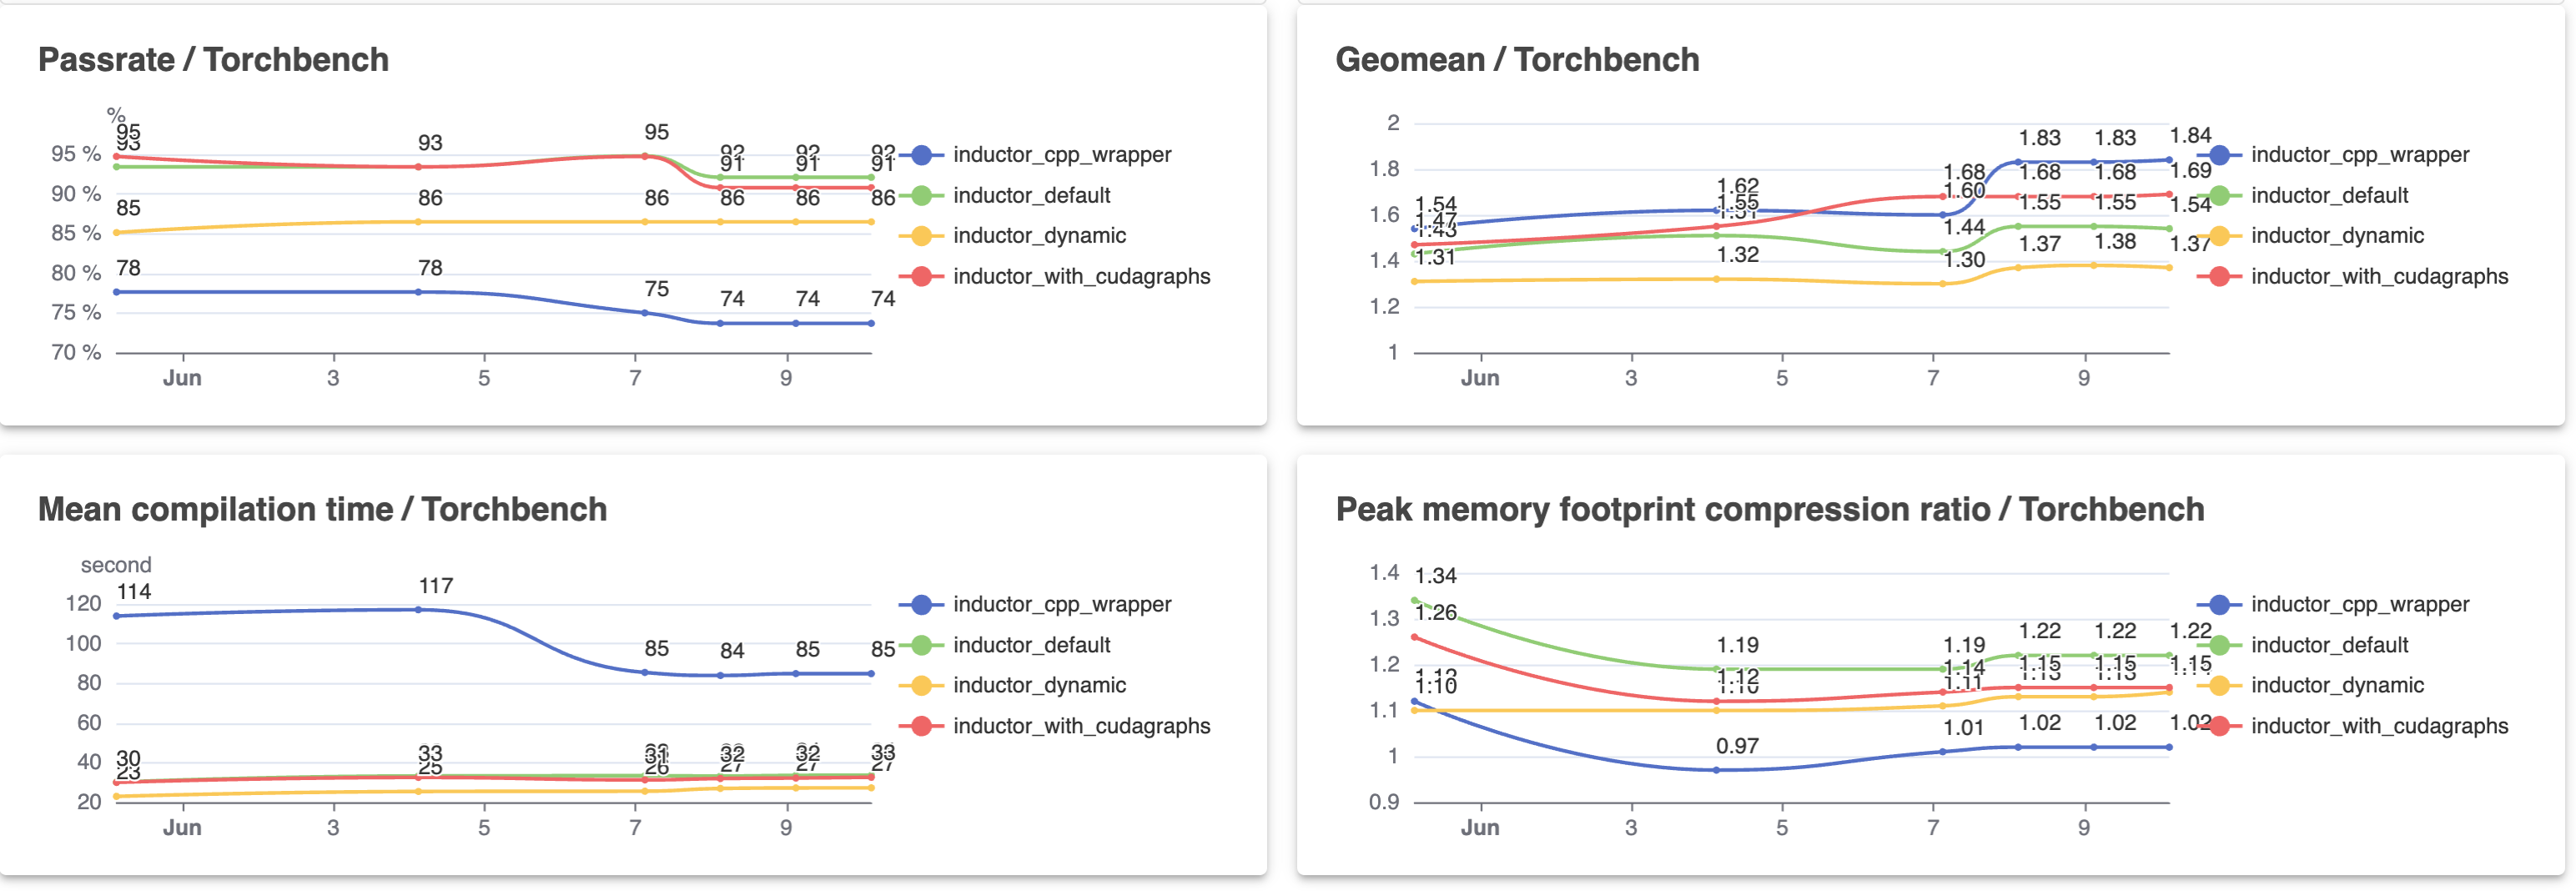


## What’s next?
- Edward: Dynamic by default
---
### Author:  [@ezyang](https://dev-discuss.pytorch.org/u/ezyang)
#### Post date: [June 20, 2023, 3:11am UTC](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/60 "2023-06-20T03:11:11Z")
# State of symbolic shapes: Jun 19 edition
Previous update: [State of symbolic shapes branch - #58 by ezyang](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777/58#state-of-symbolic-shapes-jun-10-edition-1)
## Executive summary
- **Dynamic and blueberries in the benchmark suite as model sets.** A model set (notated with the square brackets) is a subset of models from our existing benchmarks which we are aggregating separately to track something we care about. The Dynamic model set covers models which we expect dynamic shapes support to be relevant. Here is the current list, and some potential threats to validity which need follow up:
```auto
// _generate variants are good; they do E2E autoregressive
// generation and will induce varying context length.
cm3leon_generate
nanogpt_generate
hf_T5_generate
nanogpt_generate
// detection models are ok-ish; the good news is they call
// nonzero internally and exercise dynamic shapes that way,
// the bad news is we may not run enough iterations with
// varying data to get varying numbers of bounding boxes.
detectron2_fcos_r_50_fpn
vision_maskrcnn
// this recommendation model internally uses sparse tensors
// but once again its not clear that dynamic shapes is exercised
// on this sparsity
dlrm
// these language models are only running a single next
// word prediction, were NOT testing dynamic sequence length
// performance
llama
BERT_pytorch
hf_T5
// the GNN benchmarks only one run one batch so you
// arent actually triggering dynamism (and we didn't
// explicitly mark something as dynamic)
basic_gnn_edgecnn
basic_gnn_gcn
basic_gnn_gin
basic_gnn_sage
```
The blueberries set is meant to capture important LLM models, but it is very much a WIP right now.
- **Dynamic shapes by default.** We made a lot of progress. Phase 1 is completely landed in master; Phase 2 has a PR open that is passing all CI tests: [Enable automatic\_dynamic\_shapes by default by ezyang · Pull Request #103623 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/pull/103623) After discussion with CK/Xiaodong we’re also going to try YOLO’ing internal enablement here too, after I add instrumentation that will help us detect when `automatic_dynamic_shapes` triggered. I also promised gchanan that I would rename `automatic_dynamic_shapes` to something more clear, maybe `automatic_dynamic_on_recompile`. PSA: you probably don’t want `dynamic=True`, esp if you’re running into bugs; use `automatic_dynamic_shapes=True`!
- **How to test for dynamic shapes without `dynamic_shapes`**. So you want to add a new feature to PT2 but it doesn’t work with dynamic shapes. What can you do?
- Force specialization when it applies. All backends (e.g., inductor) are permitted to force extra specializations that were not strictly necessary. So if you know that you absolutely want your feature to apply, you can just specialize (e.g., by just `int()'ing` a SymInt). With dynamic shapes, you may end up with some extra int inputs in your FX graph that are actually static, but these are easy enough to ignore by testing if your input is Tensor or not. This is what we did for CUDA graphs.
- Test if there are `torch.fx.experimental.symbolic_shapes.free_symbols`. If everything is static, then there are no free symbols. This works best if you’re in some local situation where you need to decide to do something to a single tensor, but if you’re doing analysis on an FX graph it’s doable (you just may need to check multiple nodes.) This is what we did for layout optimization.
- **Notable bug fixes.**
- [Allow for sympy.Expr in tensor lowering in inductor](https://github.com/pytorch/pytorch/pull/103678) (discovered when enabling automatic dynamic everywhere)
- [Cast computation\_node\_input\_size to int](https://github.com/pytorch/pytorch/pull/103677) yolov3 automatic dynamic fix
- [Don’t apply automatic\_dynamic\_shapes if we force tensor to be static](https://github.com/pytorch/pytorch/pull/103673) major automatic dynamic bug fix; we accidentally were making parameters dynamic, which could occur when a module block was instantiated multiple times at different parameter sizes. This was probably the biggest source of failures with automatic dynamic.
- **Notable new issues.**
- [`torch.compile` error with `dynamic=True`: Found \, which is not a supported top level IR node](https://github.com/pytorch/pytorch/issues/103587) affects StableDiffusionPipeline from HuggingFace
**CI skips.** -3, -1, -1, -2 (-2, 0, 0, 0 WoW.) Regression is dlrm and hf\_T5\_generate from the switch of inference benchmarking from float32 to bfloat16, tracked at [dlrm and hf\_T5\_generate fails aot\_eager with bfloat16+dynamic\_shapes · Issue #103760 · pytorch/pytorch · GitHub](https://github.com/pytorch/pytorch/issues/103760)
**Training dashboard (as of 7b3242d5f7).** [This week on HUD](https://hud.pytorch.org/benchmark/compilers?startTime=Tue%2C%2006%20Jun%202023%2002%3A55%3A09%20GMT&stopTime=Tue%2C%2020%20Jun%202023%2002%3A55%3A09%20GMT&granularity=hour&suite=torchbench&mode=training&dtype=amp&lBranch=main&lCommit=7b3242d5f737d4a63870f8d6a008a9ae43a2fac9&rBranch=main&rCommit=daf75c07593aafc321efd652e773dd3823126743)
| Metric | Torchbench | Huggingface | TIMM models | Dynamic |
| --- | --- | --- | --- | --- |
| Passrate | 89%, 57/64 | 98%, 45/46 | 100%, 60/60 | 88%, 7/8 |
| Speedup | 1.13x → 1.11x | 1.59x | 1.18x → 1.19x | 1.29x → 1.30x |
| Comptime | 79s → 67s | 103s → 99s | 136s → 110s | 33s → 31s |
| Memory | 0.93x → 0.94x | 1.00x | 1.01x | 1.59x |
Not much to report. torchbench decrease appears to be due to a clear 10% regression on timm\_efficientdet. However, it’s unclear how real this regression is because this model has always failed accuracy. timm is within noise.


**Inference dashboard (as of 7b3242d5f7).** [This week on HUD](https://hud.pytorch.org/benchmark/compilers?startTime=Tue%2C%2006%20Jun%202023%2002%3A55%3A09%20GMT&stopTime=Tue%2C%2020%20Jun%202023%2002%3A55%3A09%20GMT&granularity=hour&suite=torchbench&mode=inference&dtype=bfloat16&lBranch=main&lCommit=7b3242d5f737d4a63870f8d6a008a9ae43a2fac9&rBranch=main&rCommit=59a01c49ee180c8d332e14bf3d5cbd1e8707bb65)
Inference was swapped to bfloat16 so… we don’t really have any point of comparison historically, because previously we were only running amp. Here’s the snapshot of data on the most recent run.
| Metric | Torchbench | Huggingface | TIMM models | Dynamic |
| --- | --- | --- | --- | --- |
| Passrate | 88%, 63/72 | 100%, 46/46 | 100%, 60/60 | 58%, 7/12 |
| Speedup | 1.52x | 1.64x | 1.72x | 1.92x |
| Comptime | 24s | 38s | 30s | 45s |
| Memory | 0.82x | 1.15x | 1.06x | 1.11x |
Some thoughts from an apples-to-oranges comparison:
- In absolute terms, the torchbench pass rate went down, but there are two models (I cannot easily tell from the display) which were removed from the suite entirely.
- PT2 is more beneficial on bfloat16 than AMP, which is expected!
- Memory compression is extremely bad. We still need to figure this out.

## What’s next?
- Edward: PSC, dynamic by default last mile and internal telemetry, maybe bug fixing if I can squeeze it in
[Previous page](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777.md?page=2)
[Next page](https://dev-discuss.pytorch.org/t/state-of-symbolic-shapes-branch/777.md?page=4)